 cloudastral
Cloud infrastructure, engineered to hold up.
Cloudastral designs, migrates, and operates cloud systems for teams that can't afford downtime. We work across AWS, Azure, and Google Cloud, pairing hands-on engineering with infrastructure as code, so every system we touch is documented, repeatable, and built to survive contact with real traffic.
From your first architecture review to day-to-day operations, you work with the same engineers the entire way — no handoffs, no account-management layer, and no mystery about what's actually running in your account.
How we build
Every environment we build starts as code.
No infrastructure we hand over depends on a console someone clicked through once. Every environment is written in Terraform, reviewed like any other code change, and reproducible from scratch if it ever needs to be.
See how we work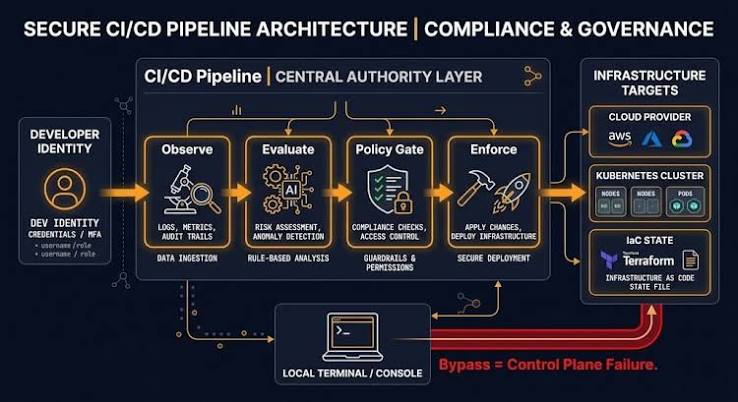
Built on the platforms you already trust
We don't default to one provider. We pick the platform — or combination of platforms — that fits your workload, and operate comfortably across all of them.
Four ways we keep your infrastructure running
Most engagements start with one of these and expand as your systems grow. Each one builds on solid architecture, so nothing you adopt later requires tearing down what came before.
See all servicesCloud Architecture & Migration
Infrastructure designed around how your product actually runs, and migrated with a tested plan instead of a leap of faith. We map dependencies, sequence the cutover in stages, and keep a rollback path ready at every point along the way.
DevOps & Automation
CI/CD pipelines and infrastructure as code that make deployments routine instead of risky. Every environment is defined in version control, so changes are reviewed, repeatable, and never tied to one engineer's memory.
Security & Compliance
Access control, monitoring, and hardened defaults built in from day one, not bolted on after an incident. We design around least-privilege access and audit-ready logging so you're never scrambling to reconstruct what happened.
Managed Cloud Operations
Ongoing monitoring, incident response, and cost tuning so your infrastructure stays healthy long after launch day. We watch the systems we build, not just the ones we're called in to fix after something breaks.
A process built for infrastructure, not guesswork
Every engagement moves through the same four stages. It's a deliberately unglamorous process — and that's the point.
Assess
We audit your current setup — architecture, costs, security gaps, single points of failure — and give you a clear, written picture of what actually needs to change and why.
Architect
We design infrastructure around your real traffic, team size, and growth plans, not a generic best-practices template pulled from a blog post. Every decision is explained, not just handed down.
Build
We implement with infrastructure as code, so every change is versioned, reviewed, and repeatable. Nothing gets clicked into existence through a console where it can't be tracked.
Operate
We stay on to monitor, maintain, and tune the system as your workload and team grow — or hand over fully documented infrastructure your own team can run with confidence.
Built to run what comes next
We're a new company, but the way we build infrastructure isn't improvised.
Every engagement follows the same disciplined defaults — infrastructure as code, documented decisions, and direct access to the engineers doing the work.
3
Cloud platforms we operate across — AWS, Azure, and Google Cloud.
100%
Of the infrastructure we build is defined as code, not clicked together.
24/7
Monitoring coverage available under managed operations.
1–2 days
Typical time to hear back from an engineer, not a queue.
Engineering-led, not account-managed
You work directly with the engineers who design and build your infrastructure — across every major cloud and the tools that hold it together.
Multi-cloud by design
We design for portability across AWS, Azure, and Google Cloud from the start, not as an afterthought bolted on later.
Kubernetes & container-native
Cluster design and day-to-day operation for workloads that need to scale predictably under real traffic.
Infrastructure as code
Every environment defined in Terraform — versioned, peer-reviewed, and reproducible on demand.
Security-first defaults
Access control and monitoring built into the architecture itself, not patched on after a close call.
Things people usually ask before reaching out
We already have infrastructure on AWS, Azure, or GCP. Do we need to start over?
No. Most engagements start with an architecture review of what you already have. We identify what's solid, what's fragile, and what's quietly costing you more than it should — then build a plan around keeping what works and replacing only what doesn't.
How long does a typical migration take?
It depends on the size and complexity of what you're moving, but most migrations are planned in phases over several weeks to a few months. Each phase has its own testing and rollback point, so nothing moves to production until it's been verified.
Do you work with early-stage startups, or only established companies?
Both. Early-stage teams usually need architecture that won't need a rewrite at their next round of growth. Established teams usually need help untangling infrastructure that grew faster than it was ever documented.
What happens after the initial build is done?
If you choose managed operations, we stay on to monitor, maintain, and tune the system as your traffic and team grow. If not, we hand over fully documented infrastructure that your own team can run independently from day one.
Which cloud platforms do you support?
AWS, Microsoft Azure, and Google Cloud, including infrastructure that spans more than one of them. We choose the platform — or combination of platforms — based on your workload and constraints, not a default preference of ours.
Have infrastructure that needs attention?
Tell us what you're running and where it's breaking. We'll tell you what we'd do about it.